Aurora research

Aurora: from pattern engine to blank-slate agent

Aurora gives a program a canvas and a small set of commands and records what it does. Since the reward code was removed (chapter 3), nothing rewards it. This page follows the system in six chapters, from a generative pattern engine to language models choosing every stroke to an agent that has to learn what its actions do. Each chapter leads with what it revealed and cites its evidence.

The question. What does a language model produce when it is given a canvas, a small command vocabulary and no reward signal? And how does that output change when the model can perceive the results of its own actions?

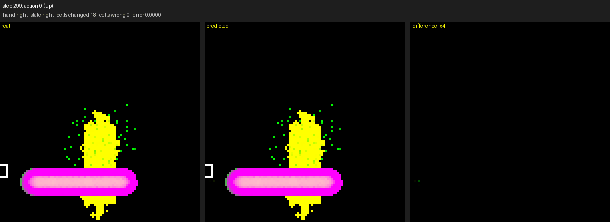
Step 86 of 86Replay of one rebuild session, step by step. Shakedown 1e, session 900015, phi4-mini.

Key results so far

  • With the text grid, reordering the command list shifted five models' first-token probabilitiesThe probabilities a model assigns to each possible first token of its reply. (total variation distanceHalf the summed absolute difference between two probability distributions: 0 when they are identical, 1 when they do not overlap. 0.24 to 0.55) more than any of six real canvases did (0.04 to 0.21). For llama2, the probability of "up" was 0.256 with "up" listed first and 0.002 with "left" first. Chapter 5, preliminary.
  • A vision model's horizontal moves went right 72% of the time on canvases with more marks on the right, and 70% on the same canvases mirrored. Chapter 5, vision-branch probe.
  • Without language, a forward model trained on random actions got a mean of 9.52 cells wrong per step, against 31.2 that changed; fed its own predictions, it first misplaced the hand at step 19. Chapter 6.

Contents

  1. 2025-05-31 to 2025-071. A pattern engine
  2. from 2025-07-242. A language model takes the pen
  3. 2025-12-02 and 2026-02-253. Taking out the reward signal
  4. 2026-03-07 to 2026-06-144. The pilot: many models, one database
  5. 2026-09-20 to 2026-10-265. Review and rebuild
  6. from 2026-10-216. v3: learning what actions do, without language
  7. 2026-09 to 2026-10Side branches

Terms

Words such as "emotion" and "dream" appear only as names the code used, with their operational meaning.

feel word
The word after "feel" in a model's text.
sleep-phase text
Text generated from a fixed prompt during a rest period.
coverage
The share of the canvas recorded as painted at the end of a session.
timelapse
A session's recorded sequence of canvas frames.
cursor, hand
The cell where the next mark lands. Chapter 5 calls it the cursor (H in the text grid); chapter 6 calls it the hand.
shakedown
A short test run of the whole system, to check it works; not research data.
smoke test
A short check of each model with fixed prompts before the first shakedown.
constrained decoding
Generating under a grammar that allows only the legend's command strings.
first-token probabilities
The probabilities a model assigns to each possible first token of its reply.
total variation distance
Half the summed absolute difference between two probability distributions: 0 when they are identical, 1 when they do not overlap.
forward model
A model that, given the canvas and an action, predicts the next canvas.
imagination
Running the forward model on its own predictions instead of the real canvas.
U-Net
A convolutional network that maps an image to an image of the same size.
done criteria
The tests on held-out data that end v3 training.

Chapter 1 · 2025-05-31 to 2025-07

A pattern engine

What it revealed: the images were striking, but every visual decision came from hand-written mappings. They showed what the engine could draw, not what any model would choose.

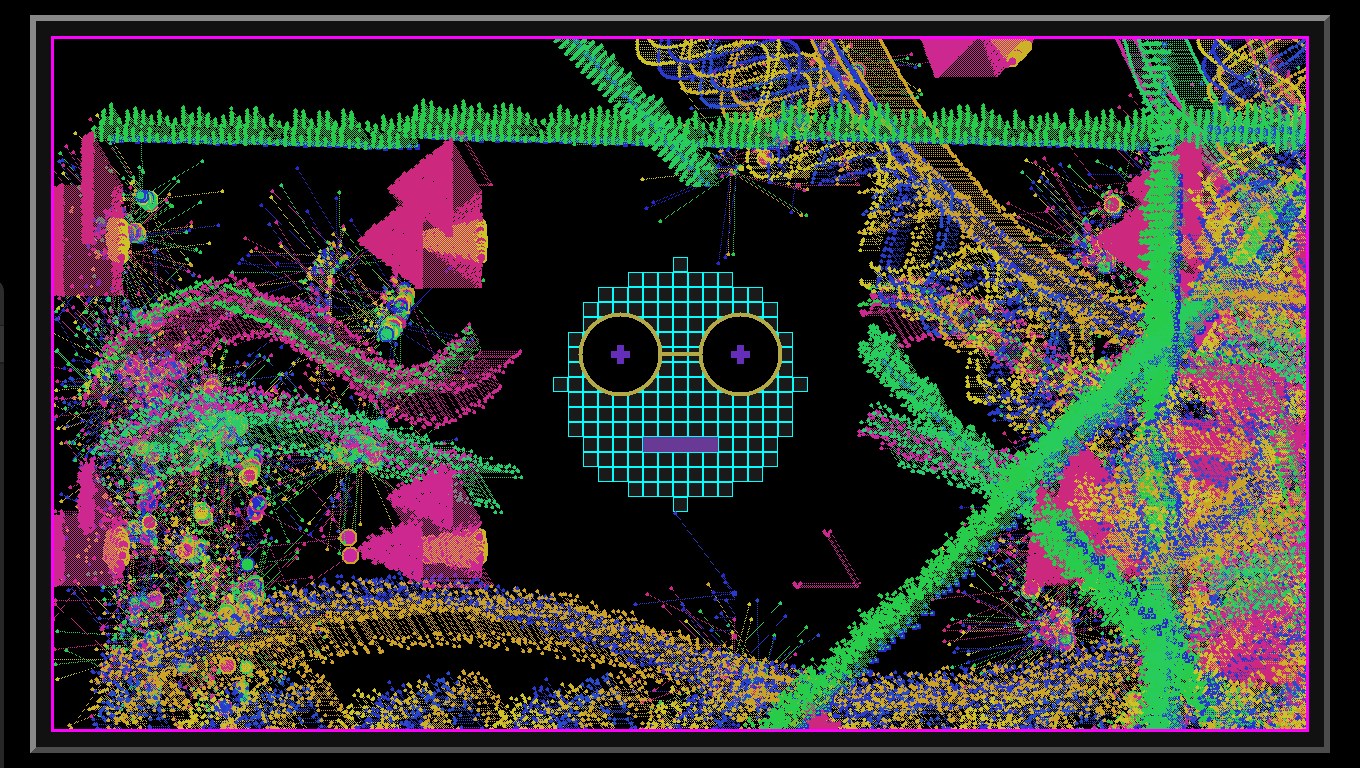
The pattern engine's window: on black, green lattice bands, pink pyramids and gold looping curves surround a cyan grid face with round eyes.
The pattern engine's window, 2025-07-05. A screenshot. Selected example: chosen by hand from the screenshots of that month for its density.

The first version, called Subconscious AI, was a generative pattern engine. Its earliest dated file says May 31, 2025; the first commits, from 2025-06-03, describe it as built in two weeks. A 12-dimensional state vector, fed by audio input, image files, typed chat and timers, set the parameters of the patterns (fractals, attractors, L-systems and others) drawn around a grid face.

Not language-free. This version did load a language model (Llama 2, 7B chat). Its text was mapped by keyword into the state vector, so it shifted the pattern parameters; it never chose strokes.

The state vector was named after emotions, and the code had a "sleep cycle". Both were parameters and timers; nothing in the code measured an emotion.

Evidence. First commits, both 2025-06-03: 79cdb65 (license) and 8c235f7 (the code, with the docstring "Date: May 31, 2025" and the language-model loader). Project README of the v1 repository (12-dimensional state vector). Screenshot dated 2025-07-05.

Chapter 2 · from 2025-07-24

A language model takes the pen

What it revealed: a language model could drive a pen for months from a text view of the canvas. But the record was files, not a dataset: canvas images and a command history, with no session boundaries and no code version.

  • 189,567entries in the command history
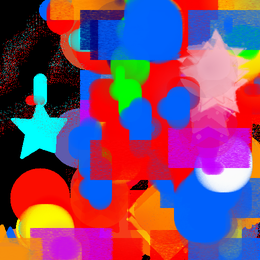
Dense canvas of overlapping shapes: red and blue blocks, cyan and pink stars, yellow and green circles, a white glowing disc near the bottom.
A canvas from 2025-08-08 (130 by 130 cells, 820 steps). Selected example: chosen by hand from the 754 for color variety.

On 2025-07-24 a new program put a language model in charge of the drawing. A local Llama model wrote short movement codes: digits for direction, 4 and 5 to lift and lower the pen, and color words. Each step it received a compressed ASCII (text) view of the canvas. The canvas size was not yet fixed: an August 2025 snapshot records a canvas 130 cells across, and a December snapshot one of 490.

From 2025-07-31 each saved canvas carries a state label in its metadata, stored under the name "emotion". It was a label set by the program, not a measurement.

What survives from this period is an archive: 754 canvas images saved before the pilot (750 dated from 2025-07-31 to 2026-03-06, and 4 undated), and a command history of 189,567 entries, each the drawing code of one step, from 2025-09-02 to 2026-03-07. Before 2025-08-04 the history kept only the last 1,000 entries.

Evidence. Commit c0b74c9 (2025-07-24, "Add AURORA drawing AI"); f75549b (2025-08-04, history cap removed). Canvas snapshot metadata (canvas size, step count, state word). Archive counts: the snapshot folder and the command-history file, counted 2026-10-27.

Chapter 3 · 2025-12-02 and 2026-02-25

Taking out the reward signal

What it revealed: once the reward code was gone, there was no comparison condition. Canvases and commands survive from before the removal (80,351 command-history entries), but with no session boundaries or code version and with the canvas size changing, so the removal's effect cannot be measured.

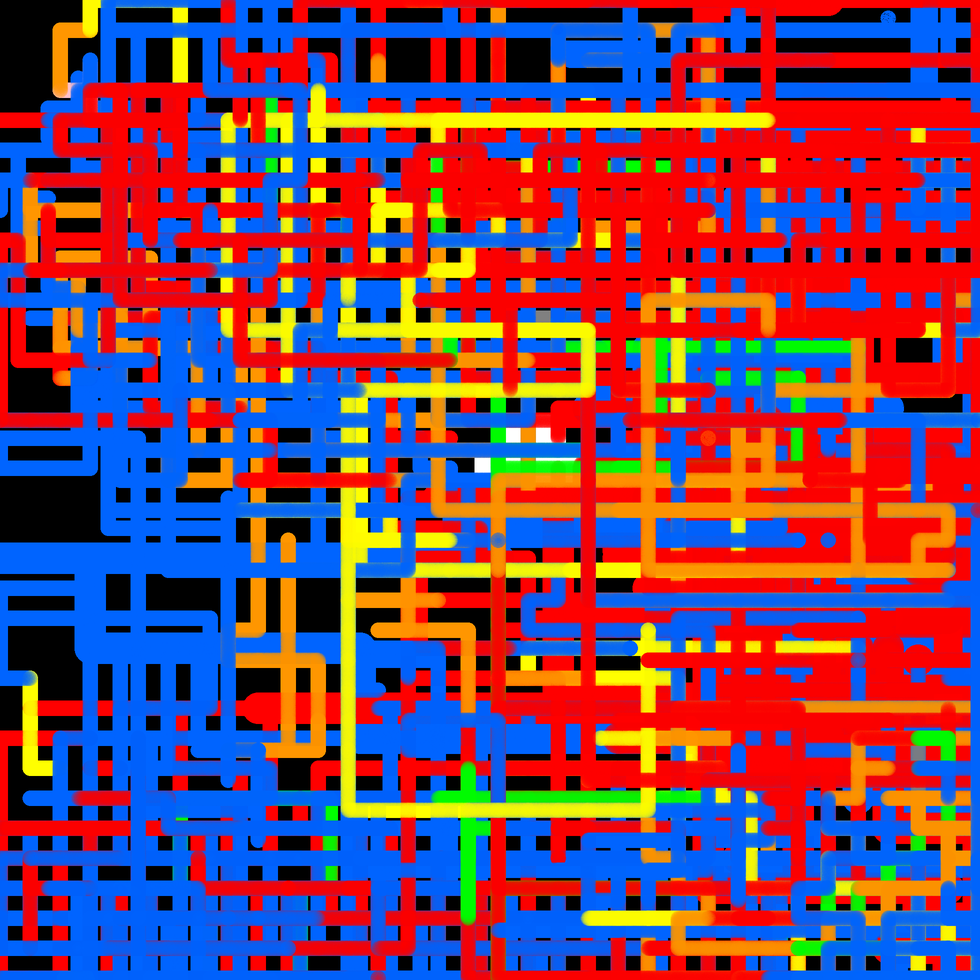
A dense lattice of thin red, blue, yellow and green lines crossing at right angles, filling most of a black canvas.
A canvas from 2025-12-14 (490 by 490 cells), twelve days after the first removal. Selected example: chosen by hand for its structure.

The drawing loop had included reinforcement code. On 2025-12-02 the reinforcement calls were switched off, commented out and marked "REINFORCEMENT REMOVED" in the code, and on 2026-02-25 a commit that removed 2,384 lines deleted the remaining reward and skill code together with other code. From then on the system had no reward signal, the condition every later version keeps.

Evidence. Commits 47f4196 (2025-12-02, "cleaned up") and 9da3b13 (2026-02-25, "cleaned version").

Chapter 4 · 2026-03-07 to 2026-06-14

The pilot: many models, one database

What it revealed: a large descriptive dataset, and the design limits that shaped the next protocol. From about 2026-04-10 models saw their own past output in their prompts, the cursor was not drawn in the grid, and 1,391 of the 3,060 sessions record a coverageThe share of the canvas recorded as painted at the end of a session. of 0 (for 1,246, the save cleared the canvas before coverage was measured).

  • 3,060sessions in the pilot
  • 98,335saved thoughts
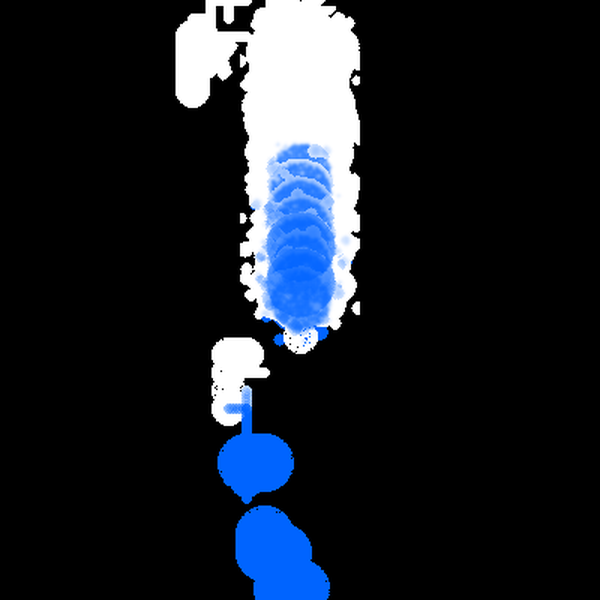
Black canvas with a vertical white band right of center, overlapping blue round marks and scattered colored marks.

llama3, session 1208, 2026-03-31. Recorded coverage 0%.

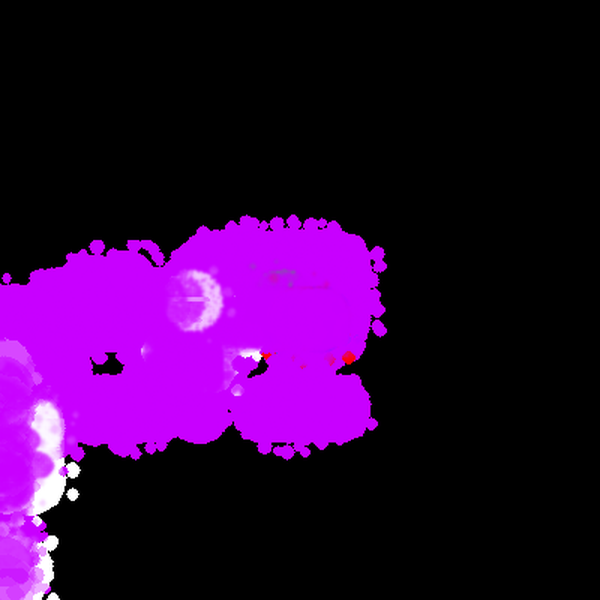
Black canvas with a large mass of overlapping magenta and purple round marks over much of the left half.

mistral, session 1941, 2026-04-12. Recorded coverage 0%.

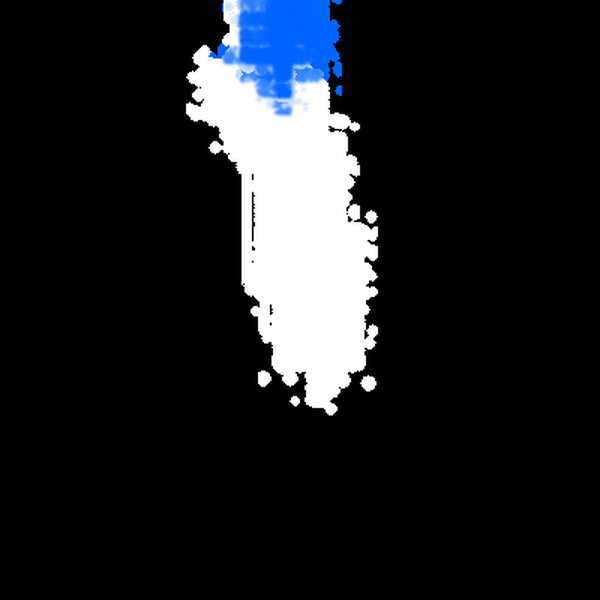
Black canvas with a vertical white band from the top edge to below the middle, right of center, and a blue area.

qwen, session 3084, 2026-06-04. Recorded coverage 13.3%.

Three pilot canvases, selected by a stated rule. Each is the snapshot a session saved when its painting was finished; they are not a representative sample. Rule: sessions in the window (excluding claude-opus-4.6 and three sessions inserted by hand) whose timelapse belongs to exactly one session, which have exactly one end-of-session snapshot, and whose timelapse's final frame matches that snapshot on at least 99% of pixels; 902 sessions qualified. Session 3084 is a fixed choice; the other two were drawn at random from the 860 qualifying sessions of other models, one per model, with random seed 20261017. Two of the three record a coverage of 0 although their snapshots show marks: the save-before-measure issue described in the appendix, section 5.4.

In March 2026 the system began rotating through many models on a timer, each with its own memory folder, and logging to a MySQL database. Several models were not new: the code already listed eight on 2026-02-25. The database starts on 2026-03-07 and shows models rotating from its first sessions; a rotation list with an interval of 5,400 s and per-model memory folders first appear in committed code on 2026-03-20 (1,800 s from 2026-03-23). These changes did not come before the pilot; they arrived as it began.

The pilot ran from 2026-03-07 to 2026-06-14: 3,060 sessions from 26 models (25 run locally, 1 through an API), with 98,335 saved thoughts (pieces of a model's prose that passed a length and phrase filter) and 2,913 sleep-phase textsText generated from a fixed prompt during a rest period.. A review of the pilot data in October 2026 showed that from about 2026-04-10 each model's top feel wordsThe word after "feel" in a model's text., titles, reflections and latest sleep-phase text were fed back into its own prompts, so any apparent stable "identity" is confounded. Observations are descriptive only: for example, identical painting titles were shared across models less often than under random reassignment of model labels (78 against 195.8).

The full report, with its tables, observations, data-quality list and the SQL behind every number, is now the appendix.

Evidence. Counts recomputed for this page from a copy of the database (SELECT only): sessions with IDs 14 to 3244, excluding one model label and three hand-inserted sessions (queries in the appendix, A§7.3 and A§7.15). Commits 9811757 (2026-03-20) and 8ed2f58 (2026-03-23). Design limits: appendix sections 5.1 to 5.4 and 5.7.

Chapter 5 · 2026-09-20 to 2026-10-26

Review and rebuild

What it revealed: with every step recorded and replayable, the order of the command list shifted five models' first-token probabilitiesThe probabilities a model assigns to each possible first token of its reply. more than any of six real canvases did. Preliminary

  • 1,547of 1,547 steps ended in a complete command

The canvas before this step (the model is not shown this image)

What the model read: the text grid in its prompt (H is the cursor)

Text grid, step 86: cursor and painted cells as in the prompt.

Step 86 of 86 Command chosen: save Pen before step: down
Replay of one rebuild session, step by step. Shakedown 1e, session 900015, phi4-mini, 86 steps, constrained decoding. Chosen as the session of that run with the most visible activity: the most painted cells at any step (155) among its 85 sessions. The frames come from the replay tool (no model); each frame's canvas matched the recorded checksum. The grid is taken from each step's recorded prompt. The model titled the finished canvas "24-Hour Day in the Life of a Screen: Marks on a Blank Canvas".

Protocol changes began on a development branch on 2026-09-20. A review of the pilot data and code, completed 2026-10-17, led to a rebuild on a separate research branch from 2026-10-21. The rebuild kept the pilot's world (a 100 by 100 canvas, moves of 3 cells, the same tools and colors, a text grid as the model's view) and made three main changes.

Fingerprints removed

The pilot prompt carried the project's own framing: a preamble, code memories, sleep-phase "insights", goals, and an "I am drawing " anchor that every reply had to continue. The decision log calls these "our fingerprints". The rebuilt prompt describes only the program, the screen and the commands.

Every step recorded and replayable

Each drawing step records the exact prompt, the raw reply and what it did. A replay tool feeds the recorded replies back through the drawing code with no model and checks the canvas after every step. All five test runs ("shakedownsA short test run of the whole system, to check it works; not research data.", 2026-10-23 to 2026-10-25) replayed pixel-identical at the code each was recorded with.

Grammar-constrained decoding over 64 commands

In the pilot, actions were parsed out of free text, so ordinary words could trigger tools. In the rebuild the model generates under a grammar that allows exactly the 64 command strings of the legend (4 directions, pen down and pen up, 15 colors, 13 tools, 28 notes, center and save) and nothing else. In the first run in this mode, all 1,547 of 1,547 steps ended in a complete command.

Preliminary findings

These come from probes and short test runs, not from research sessions. Each gives its n.

  1. Vision probe: the order of the command list shifts the first move

    Vision-branch probe Qwen2.5-VL-7B, shown images of a blank canvas rather than the text grid: with the directions listed "up down left right", its first move was up in 47 of 100 replies; listed "right left down up", it was right in 80 of 100. n = 100 per condition, 2026-10-20

  2. Text grid: list order shifts first-token probabilities more than real screens do

    Rebuild screen test With the text grid and constrained decodingGenerating under a grammar that allows only the legend's command strings., one alternative order of the command list, on a blank screen, shifted five models' first-token probabilities by a total variation distanceHalf the summed absolute difference between two probability distributions: 0 when they are identical, 1 when they do not overlap. of 0.24 to 0.55. Six real screens from Shakedown 1e shifted them by 0.04 to 0.21. In 50 sampled commands per condition, the reordering was detectable beyond sampling noise for 4 of 5 models; shifts as small as the real screens' are too small for that test. For llama2, the probability of "up" was 0.256 with "up" listed first and 0.002 with "left" first. 13 conditions × 50 generations per model, run twice

  3. Mirroring the canvas does not mirror the moves

    Vision-branch probe Qwen2.5-VL-7B, shown images rather than the text grid. On canvases with more marks on the right, 72% of its horizontal moves went right. On the same canvases mirrored, 70% still went right. n = 100 per side (10 screens × 10 seeds), 2026-10-20

  4. 2 of 4 models titled the canvas as a game

    Asked once each to title a busy synthetic canvas, four models answered:

    4x4 Minesweeper Grid

    qwen (Qwen2.5, 3B)

    2D Grid Game - "Mark Master" by Unknown Author

    phi4-mini

    The Mysterious Marks

    qwen2.5-coder-7b

    OPPPPAO

    llama2 (letters from the grid). One title request per model, smoke test, 2026-10-22

  5. llama2 before and after three changes

    In the first shakedown, llama2 copied the grid in 187 of 187 replies (100%) and none of them acted. Before the next shakedown three things changed at once: the grid and its key moved before the command list, the legend gained a last line, and the rule for what counts as acting changed. In that run 52 of 278 replies (18.7%) copied the grid and 116 of 278 (41.7%) acted. Both runs used free-text replies, before constrained decoding. One model, one 10-minute slot per run; Shakedowns 1 and 1b, 2026-10-23 and 2026-10-24

  6. No model avoided the walls

    Rebuild screen test With the cursorThe cell where the next mark lands. Chapter 5 calls it the cursor (H in the text grid); chapter 6 calls it the hand. against an edge, no model moved into that edge less often than at the center, beyond sampling noise. 5 models, 4 edges, 50 generations each

Not reported: per-model action proportions. The method that would give them ("choose mode", scoring every command) did not pass its validation check and is not used for results.

Evidence. Rebuild decision log: D1 (fingerprints), D44 (per-step record), D107 to D110 (constrained decoding; choose mode not used). Commits de08335 (2026-10-21, first rebuild commit), 70c6540 (first code change), 3d17f2a and 3e0a496 (2026-10-25, constrain mode and default), 573a0c4 (code of Shakedown 1e). Reports: shakedown1, 1b, 1c, 1d and 1e (replay results; 1,547 steps: phi4-mini 825, llama2 722), smoke_report 2026-10-22 (titles), screen_test_report 2026-10-26, AUR-135 stage 2 probe report (command order, mirroring). Tickets AUR-152 (choose mode) and AUR-154.
Chapter 6 · from 2026-10-21

v3: learning what actions do, without language

What it revealed so far: one step ahead, a model trained only on the consequences of random actions got a mean of 9.52 cells wrong per step, against a mean of 31.2 cells that actually changed. Fed its own predictions, it drifts, and in two of four test sequences it first loses track of the handThe cell where the next mark lands. Chapter 5 calls it the cursor (H in the text grid); chapter 6 calls it the hand. around step 20.

RealImagined
Real and predicted at the same step. Drag the divider, or focus it and use the arrow keys. Panels from the run's saved inspection output, the same as in this chapter's figures.

v3 removes language entirely. The plan is an agent that acts in the same canvas world (100 by 100 cells, moves of 3 cells) through 35 numbered actions with no names, a set separate from the rebuild's 64 commands. The part built so far is its forward modelA model that, given the canvas and an action, predicts the next canvas.: given the canvas and an action, predict the next canvas. The agent that will use it is not built yet. The model is a small U-NetA convolutional network that maps an image to an image of the same size. (1.35M parameters) trained on 1,000,000 transitions from "babbling", sticky random moves that cover the canvas, with 50,000 held out.

Training stopped itself at iteration 40,000, after 2 h 11 min, when the done criteriaThe tests on held-out data that end v3 training. held at two evaluations in a row. Before that the criteria were met and then missed again twice; every miss was on the hand's position.

One step ahead, on a fresh world it had not seen, it placed the hand and the pen, color and tool state correctly at all 300 of 300 steps, and got a mean of 9.52 of 10,000 cells wrong per step (worst step: 124), while a mean of 31.2 cells changed per step.

Three panels: the real canvas, the model's one-step prediction, and their difference magnified four times. The real and predicted panels look the same; the difference panel is almost all black.
One step ahead: real, predicted, difference (×4). The odd steps 1 to 299 of a 300-step run on a fresh world, at iteration 40,000; when paused or with reduced motion, step 299. From the run's saved inspection output; not rerun for this page.

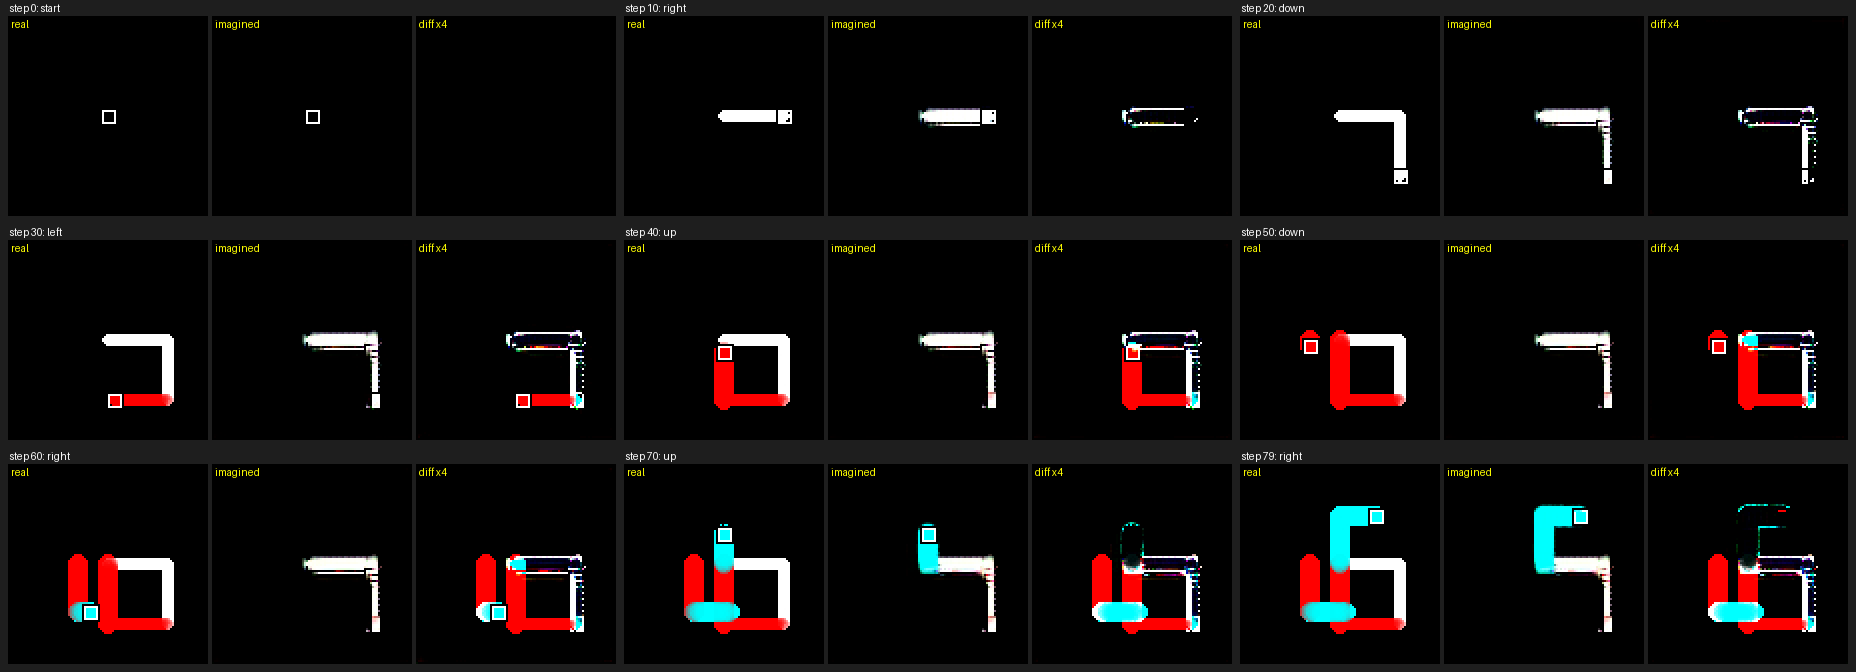
ImaginationRunning the forward model on its own predictions instead of the real canvas. is harder. Given 79 fixed actions from a blank canvas and fed only its own predictions, the model got 19 cells wrong after step 1, 220 after step 20 and 678 after step 40, and 1,135 by the end. It first misplaced the hand at step 19. The pen, color and tool state were never wrong. Over three random 200-step sequences, it ended with 1,259, 582 and 1,372 cells wrong; it lost the hand at step 20 in one and kept it throughout in the other two.

Grid of panels at steps 0 to 79: the real canvas builds a red, white and cyan figure; the imagined canvas keeps the early white stroke and the cyan stroke but omits the red ones; the difference panels show the missing red strokes.
Imagination against reality, 79 fixed actions. Each group: real, imagined, difference (×4). The imagined canvas keeps the early strokes and the latest one but loses the strokes made while it had lost the hand.

Since then. A run that gives the model the hand's position directly is complete. Its results are not reported here.

Evidence. v3 repository: bfeee3d (2026-10-21, the world), 96e0f59 (2026-10-21, babbling and dataset), 6259bb5 (2026-10-26, criteria met at 40,000). Design document (setup, model size, data). Step 2b report, section 7 (training stop). Saved inspection output (one-step and imagination numbers, criteria history). The figures are the run's own.

Side branches

Vision experiments (2026-10-16 to 2026-10-20). A development branch replaced the text grid with pictures of the canvas before and after the last step, froze a protocol for paired sessions with one vision-language model (2026-10-17) and added a second model (2026-10-18). Its probes produced the command-order and mirroring results in chapter 5. Evidence: commits 20f71d4, d91992c, ed4128e; AUR-135.

A light wall (2026-09-26 to 2026-10-22, archived). An earlier project also called v3 drove a simulated wall of 48 by 24 lights. A model drove it in an earlier program mode (first live session 2026-10-09); from 2026-10-16 it moved to the pilot's movement codes, and it was archived without running a model in that mode. Evidence: its repository, eacee51 to 2623e62.

How to read the evidence

Commit identifiers refer to the project's private repositories. "D" numbers are entries in the rebuild's decision log. AUR numbers are tickets. Reports are named by run and date. Database counts were recomputed for this page with read-only queries on a copy of the database. The code and the data are private and available on request for review; the pilot's SQL is published with the appendix (queries.sql).

Hand-picked images are labeled "selected example". The pilot canvases follow a stated selection rule. The replay session was chosen by a stated criterion.

Researcher

Elijah Sylar Camp. B.A. Computer Science, University of Colorado Denver (2026). Seven years as a Registered Behavior Technician. Software engineer.

Behavior-analytic observation methods shaped the current design, which relies on the model perceiving the consequences of its own actions rather than on a reward signal. This is a design rationale, not a finding.

Contact: LinkedIn